GPUs
NVIDIA RTX 2000E Ada 16 GB review: a 50 W low-profile card for local AI
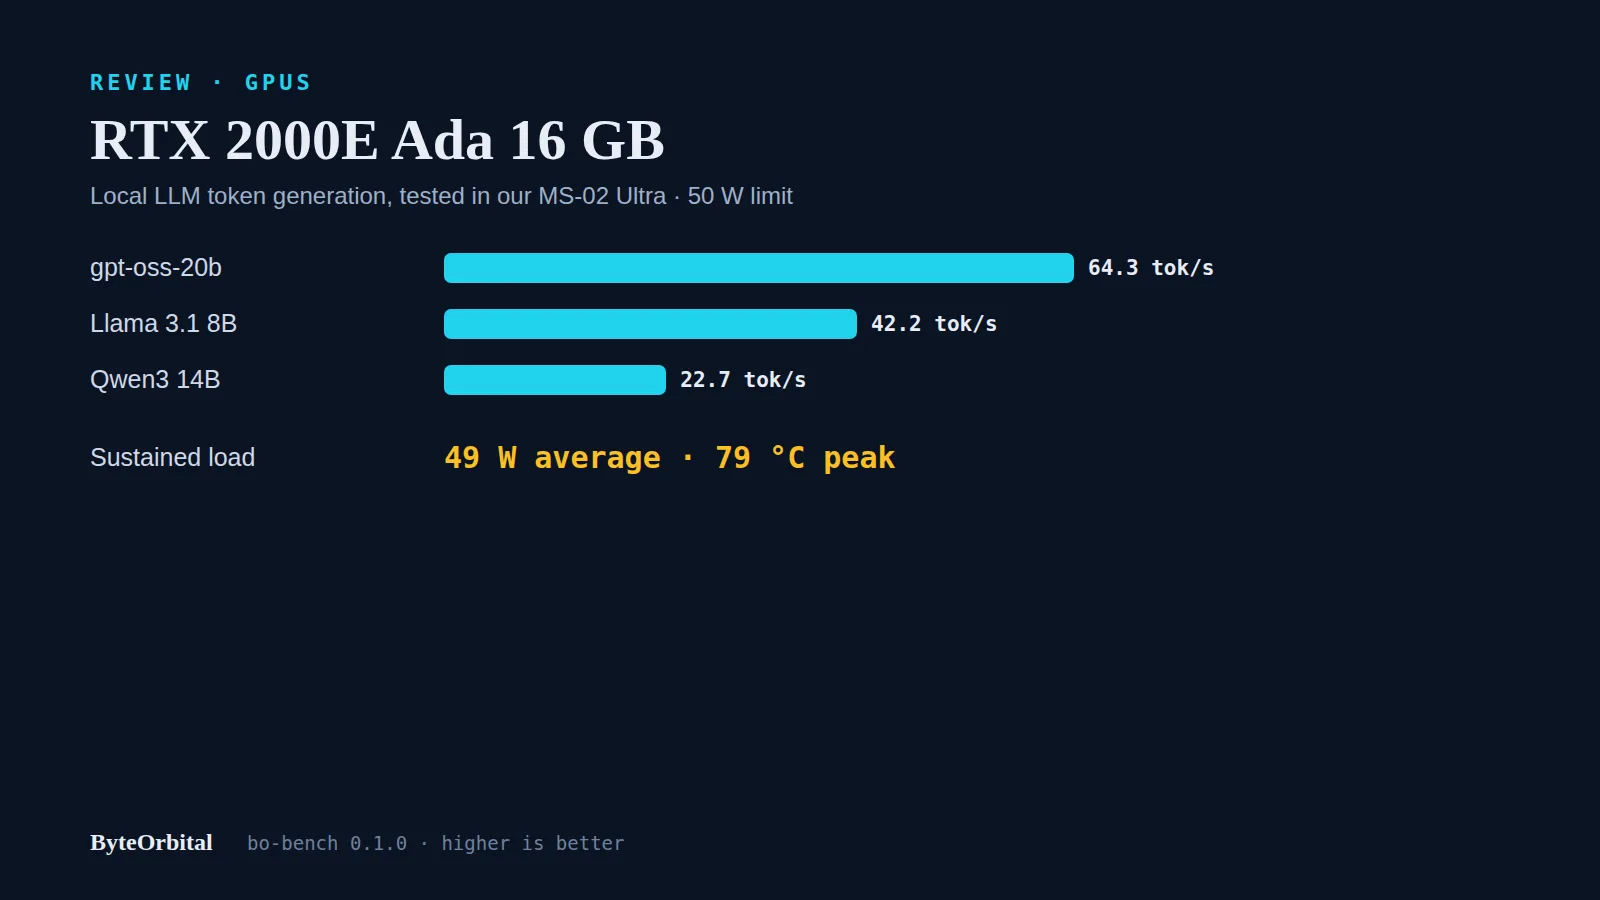
Tested inside our Minisforum MS-02 Ultra. Sixteen gigabytes runs 8B to 20B models comfortably at about 60 tok/s, draws roughly 49 W flat out, and stops at the 30B class.
Topic
Every ByteOrbital article about Local AI.
Tested inside our Minisforum MS-02 Ultra. Sixteen gigabytes runs 8B to 20B models comfortably at about 60 tok/s, draws roughly 49 W flat out, and stops at the 30B class.
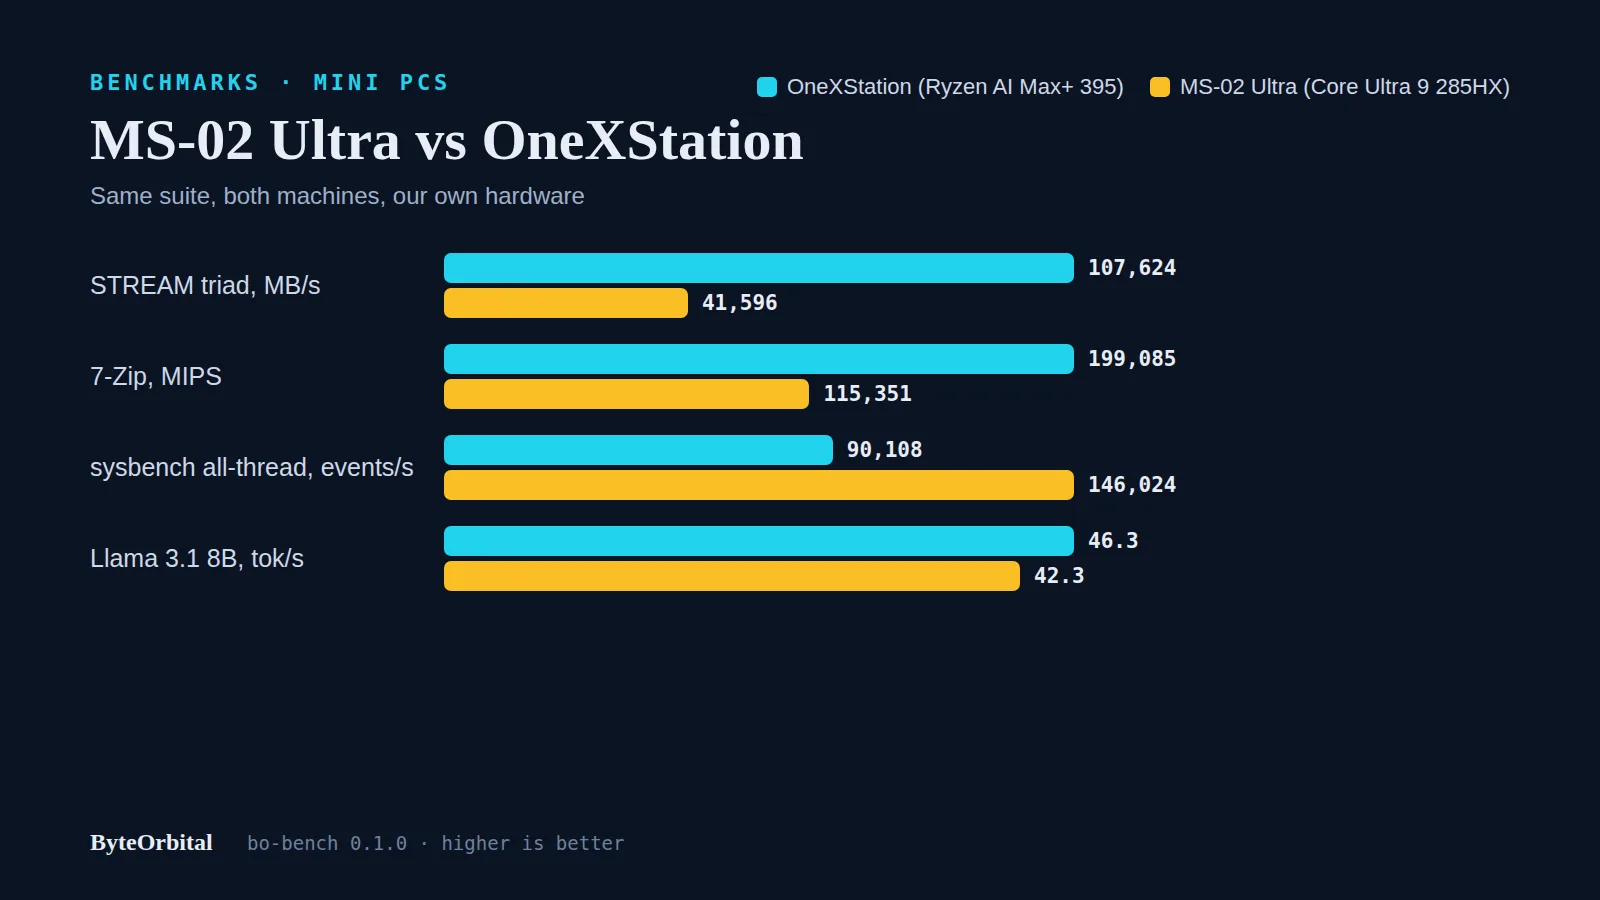
We ran the same benchmark suite on both machines. The Ryzen AI Max+ box holds far bigger models and runs them faster; the Intel box wins at all-thread CPU work and Postgres, and keeps a swappable GPU.
Minisforum has announced the MS-S1 MAX-P495, a compact local AI machine built around AMD's Ryzen AI Max+ PRO 495, but has given no price or release date.
17:40
How much memory a model really needs: weights, quantisation, the KV cache and overhead, with every figure computed by a script you can run.
17:40
Unified memory or a discrete GPU? A buyer's framework built on memory capacity, bandwidth, power and noise, using published specifications.
17:40
Why memory bandwidth, not headline TOPS, sets how fast a local model talks, and where each kind of processor earns its place.
17:40
What local AI actually is, what hardware it asks for, and how llama.cpp, Ollama, LM Studio, vLLM and MLX differ.
7 articles