Benchmarks run by ByteOrbital on our own hardware; written with AI assistance from our results.
Two compact machines are now serious options for running language models at home. The Minisforum MS-02 Ultra pairs an Intel Core Ultra 9 285HX with a low-profile NVIDIA card. The OneXStation i1 puts an AMD Ryzen AI Max+ 395 and its Radeon 8060S on 128 GB of memory that the CPU and GPU share. We own both, use them daily, and ran an identical suite on each.
Prefer to watch? Nova and Dex run through every chart in our six-minute video on YouTube.
How we tested
CPU
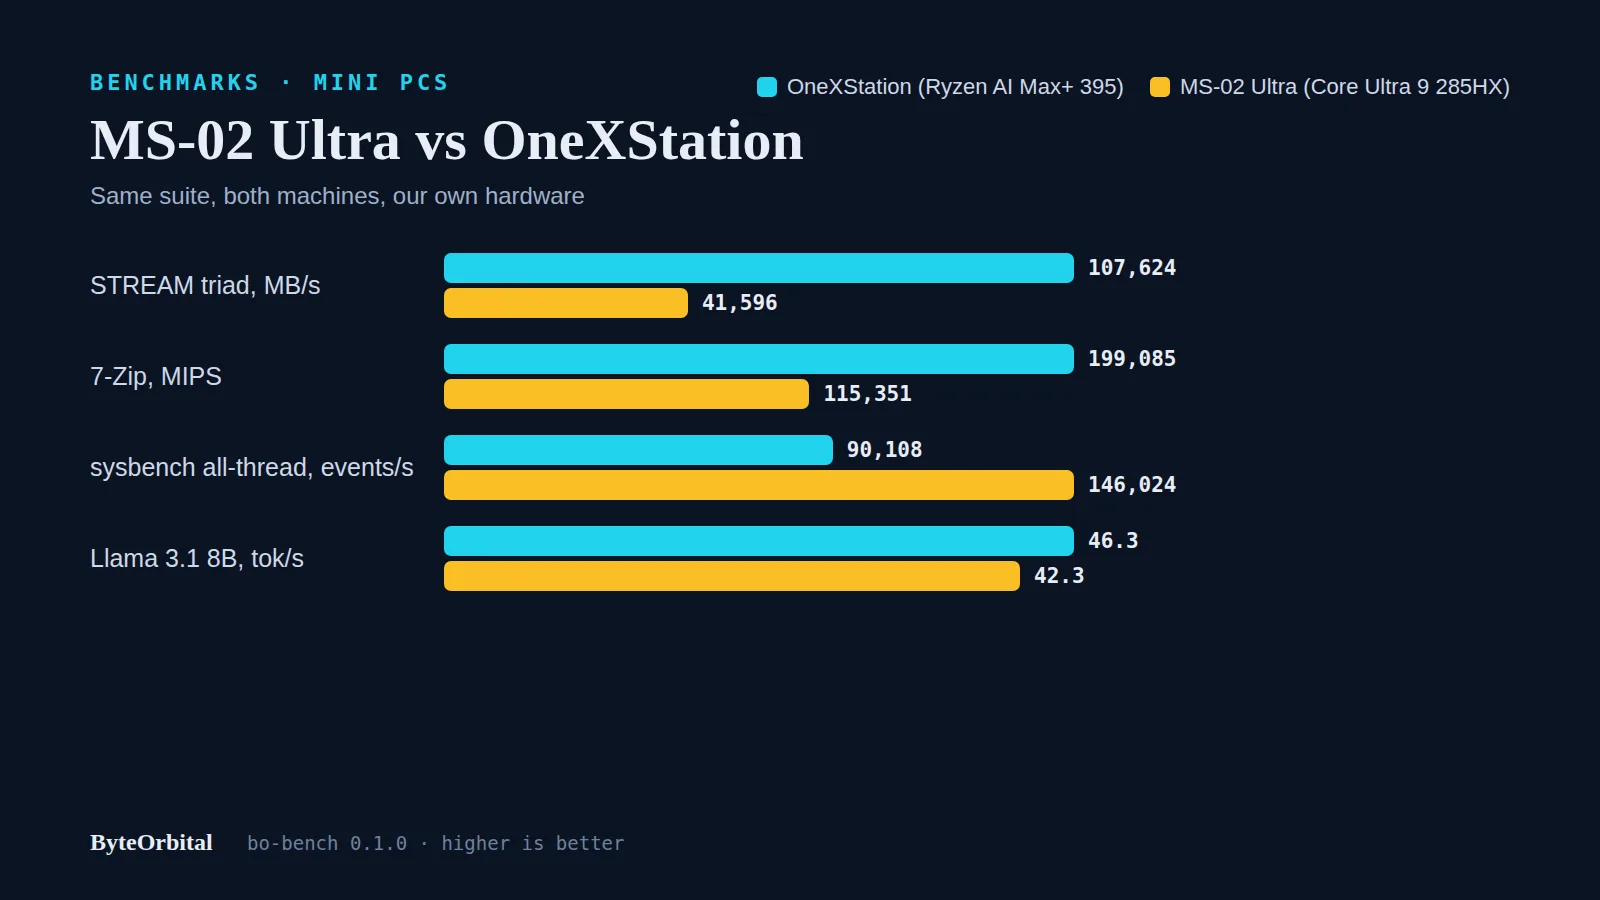
The CPU results do not give one winner. On 7-Zip the OneXStation scores 199,085 MIPS against 115,351 (73% ahead), and its decompression score is 222,087 against 106,227. It also leads single-thread sysbench (5,790 vs 4,423 events/s), x264 (314 vs 233 fps) and x265 (120 vs 99.0 fps). Yet on all-thread sysbench the MS-02 Ultra scores 146,024 against 90,108 events/s, and on Blender CPU rendering it takes 60.1 s against 64.3 s. Building the Linux kernel is a draw: 57.7 s on the OneXStation, 59.2 s on the MS-02 Ultra.
OneXStation (8060S) is 73% faster than MS-02 Ultra at 7-Zip compression
7-Zip benchmark, all threads. · MIPS · higher is better
View data table
| Series | Value (MIPS) | Runs | Min to max | Std dev | Version | Command |
|---|---|---|---|---|---|---|
| MS-02 Ultra | 115,351 | 3 | 112,220 to 117,077 | 2,462 | p7zip-full from Ubuntu apt (7z b) | 7z b -mmt=24 |
| OneXStation (8060S) | 199,085 | 3 | 198,654 to 199,526 | 436 | p7zip-full from Ubuntu apt (7z b) | 7z b -mmt=32 |
MS-02 Ultra is 62% faster than OneXStation (8060S) at all-thread CPU speed
bo-bench sysbench multi. · events/s · higher is better
View data table
| Series | Value (events/s) | Runs | Min to max | Std dev | Version | Command |
|---|---|---|---|---|---|---|
| MS-02 Ultra | 146,024 | 3 | 146,013 to 146,486 | 270 | sysbench from Ubuntu apt | sysbench cpu --threads=24 --time=15 run |
| OneXStation (8060S) | 90,108 | 3 | 90,014 to 90,804 | 431 | sysbench from Ubuntu apt | sysbench cpu --threads=32 --time=15 run |
Memory
This is where the unified-memory design shows. STREAM copy runs at 146,172 MB/s on the OneXStation and 57,955 MB/s on the MS-02 Ultra; triad is 107,624 against 41,596 MB/s. The MS-02's memory is 2 x 32 GB DDR5 rated at 5600 MT/s but running at 4800 MT/s, so these figures use the configured speed, and we have not tested at the rated one. The OneXStation's LPDDR5 runs at its rated 8000 MT/s. Latency is more even: at 1 GiB it is 175 ns on the MS-02 against 177 ns on the OneXStation, with the MS-02 faster in the small caches (1.02 ns against 1.46 ns at 32 KiB).
OneXStation (8060S) wins every memory bandwidth test, by 152-203%
STREAM, all threads. Copy, scale, add and triad are the four standard STREAM kernels. · GB/s · higher is better
+159% vs MS-02 Ultra OneXStation (8060S) leads in 4 of 4
View data table
| Series | Test | Value (GB/s) | Runs | Min to max | Std dev | Version | Command |
|---|---|---|---|---|---|---|---|
| MS-02 Ultra | Copy | 58 | 3 | 57.9 to 58 | 0.036 | stream.c (virginia.edu, sha pinned in assets.lock.json), gcc from apt | cd /var/tmp/bo-bench/stream && OMP_NUM_THREADS=24 OMP_PROC_BIND=spread ./stream |
| MS-02 Ultra | Scale | 36.7 | 3 | 36.6 to 36.7 | 0.065 | stream.c (virginia.edu, sha pinned in assets.lock.json), gcc from apt | cd /var/tmp/bo-bench/stream && OMP_NUM_THREADS=24 OMP_PROC_BIND=spread ./stream |
| MS-02 Ultra | Add | 41.6 | 3 | 41.5 to 41.6 | 0.055 | stream.c (virginia.edu, sha pinned in assets.lock.json), gcc from apt | cd /var/tmp/bo-bench/stream && OMP_NUM_THREADS=24 OMP_PROC_BIND=spread ./stream |
| MS-02 Ultra | Triad | 41.6 | 3 | 41.6 to 41.6 | 0.03 | stream.c (virginia.edu, sha pinned in assets.lock.json), gcc from apt | cd /var/tmp/bo-bench/stream && OMP_NUM_THREADS=24 OMP_PROC_BIND=spread ./stream |
| OneXStation (8060S) | Copy | 146 | 3 | 146 to 146 | 0.029 | stream.c (virginia.edu, sha pinned in assets.lock.json), gcc from apt | cd /var/tmp/bo-bench/stream && OMP_NUM_THREADS=32 OMP_PROC_BIND=spread ./stream |
| OneXStation (8060S) | Scale | 111 | 3 | 111 to 111 | 0.057 | stream.c (virginia.edu, sha pinned in assets.lock.json), gcc from apt | cd /var/tmp/bo-bench/stream && OMP_NUM_THREADS=32 OMP_PROC_BIND=spread ./stream |
| OneXStation (8060S) | Add | 108 | 3 | 108 to 108 | 0.054 | stream.c (virginia.edu, sha pinned in assets.lock.json), gcc from apt | cd /var/tmp/bo-bench/stream && OMP_NUM_THREADS=32 OMP_PROC_BIND=spread ./stream |
| OneXStation (8060S) | Triad | 108 | 3 | 108 to 108 | 0.031 | stream.c (virginia.edu, sha pinned in assets.lock.json), gcc from apt | cd /var/tmp/bo-bench/stream && OMP_NUM_THREADS=32 OMP_PROC_BIND=spread ./stream |
Storage
The drives differ, so this compares drives rather than platforms. The OneXStation has a 1 TB Acer Predator GM7; the MS-02 Ultra carries a Samsung 990 PRO 1 TB and a Crucial P310 1 TB. Sequential read is 7,226 MB/s (990 PRO), 7,064 MB/s (P310) and 6,910 MB/s (GM7). The GM7 also has the lowest queue-depth-1 read latency: 37.6 µs median against 48.4 µs for the P310 and 54.5 µs for the 990 PRO. Write results on the MS-02 varied too much while its services were running to quote fairly, so we are testing all three drives properly on their own for a separate SSD round-up.
GPU, encode and homelab
For hardware video encoding the OneXStation's VAAPI HEVC path reaches 755 fps (31.5x real time) and H.264 reaches 441 fps. On the MS-02 Ultra, NVENC HEVC does 371 fps and the Intel iGPU's VAAPI HEVC does 405 fps by default, 451 fps in our RTX-card configuration. The RTX card also does AV1 at 393 fps. We ran Blender GPU rendering only on the MS-02: 26.9 s on CUDA and 13.0 s on OptiX for the BMW scene. We have no GPU speech-to-text run for the OneXStation, but on CPU it manages 3.78x real time against 2.68x for the MS-02.
OneXStation (8060S) tops hardware video encoding: 755 fps (vaapi_hevc)
Big Buck Bunny 1080p, 60 s source. · fps · higher is better
+4.6% vs MS-02 Ultra - igpu_arc MS-02 Ultra - ada_cuda leads in 2 of 7
View data table
| Series | Test | Value (fps) | Runs | Min to max | Std dev | Version | Command |
|---|---|---|---|---|---|---|---|
| MS-02 Ultra | nvenc_hevc | 371 | 3 | 368 to 371 | 1.97 | distro ffmpeg (see inventory) | ffmpeg -hide_banner -benchmark -y -t 60 -i /var/tmp/bo-bench/assets/bbb-clip/bbb_1080p_60s.mp4 -an -c:v hevc_nvenc -preset p5 -b:v 6M -f null - 2>&1 | tr '\r' '\n' |
| MS-02 Ultra | intel_vaapi_h264 | 389 | 3 | 387 to 401 | 7.69 | distro ffmpeg (see inventory) | ffmpeg -hide_banner -benchmark -y -t 60 -i /var/tmp/bo-bench/assets/bbb-clip/bbb_1080p_60s.mp4 -an -vaapi_device /dev/dri/renderD128 -vf format=nv12,hwupload -c:v h264_vaapi -b:v 8M -f null - 2>&1 | tr '\r' '\n' |
| MS-02 Ultra | intel_vaapi_hevc | 405 | 3 | 397 to 424 | 13.6 | distro ffmpeg (see inventory) | ffmpeg -hide_banner -benchmark -y -t 60 -i /var/tmp/bo-bench/assets/bbb-clip/bbb_1080p_60s.mp4 -an -vaapi_device /dev/dri/renderD128 -vf format=nv12,hwupload -c:v hevc_vaapi -b:v 6M -f null - 2>&1 | tr '\r' '\n' |
| MS-02 Ultra - ada_cuda | nvenc_hevc | 371 | 3 | 369 to 371 | 1.51 | distro ffmpeg (see inventory) | ffmpeg -hide_banner -benchmark -y -t 60 -i /var/tmp/bo-bench/assets/bbb-clip/bbb_1080p_60s.mp4 -an -c:v hevc_nvenc -preset p5 -b:v 6M -f null - 2>&1 | tr '\r' '\n' |
| MS-02 Ultra - ada_cuda | intel_vaapi_h264 | 414 | 3 | 409 to 425 | 8.19 | distro ffmpeg (see inventory) | ffmpeg -hide_banner -benchmark -y -t 60 -i /var/tmp/bo-bench/assets/bbb-clip/bbb_1080p_60s.mp4 -an -vaapi_device /dev/dri/renderD128 -vf format=nv12,hwupload -c:v h264_vaapi -b:v 8M -f null - 2>&1 | tr '\r' '\n' |
| MS-02 Ultra - ada_cuda | intel_vaapi_hevc | 451 | 3 | 451 to 466 | 8.73 | distro ffmpeg (see inventory) | ffmpeg -hide_banner -benchmark -y -t 60 -i /var/tmp/bo-bench/assets/bbb-clip/bbb_1080p_60s.mp4 -an -vaapi_device /dev/dri/renderD128 -vf format=nv12,hwupload -c:v hevc_vaapi -b:v 6M -f null - 2>&1 | tr '\r' '\n' |
| MS-02 Ultra - ada_cuda | nvenc_h264 | 322 | 3 | 319 to 322 | 1.36 | distro ffmpeg (see inventory) | ffmpeg -hide_banner -benchmark -y -t 60 -i /var/tmp/bo-bench/assets/bbb-clip/bbb_1080p_60s.mp4 -an -c:v h264_nvenc -preset p5 -b:v 8M -f null - 2>&1 | tr '\r' '\n' |
| MS-02 Ultra - ada_cuda | nvenc_av1 | 393 | 3 | 392 to 393 | 0.556 | distro ffmpeg (see inventory) | ffmpeg -hide_banner -benchmark -y -t 60 -i /var/tmp/bo-bench/assets/bbb-clip/bbb_1080p_60s.mp4 -an -c:v av1_nvenc -preset p5 -b:v 5M -f null - 2>&1 | tr '\r' '\n' |
| MS-02 Ultra - igpu_arc | intel_vaapi_h264 | 400 | 3 | 398 to 412 | 7.76 | distro ffmpeg (see inventory) | ffmpeg -hide_banner -benchmark -y -t 60 -i /var/tmp/bo-bench/assets/bbb-clip/bbb_1080p_60s.mp4 -an -vaapi_device /dev/dri/renderD128 -vf format=nv12,hwupload -c:v h264_vaapi -b:v 8M -f null - 2>&1 | tr '\r' '\n' |
| MS-02 Ultra - igpu_arc | intel_vaapi_hevc | 427 | 3 | 414 to 441 | 13.4 | distro ffmpeg (see inventory) | ffmpeg -hide_banner -benchmark -y -t 60 -i /var/tmp/bo-bench/assets/bbb-clip/bbb_1080p_60s.mp4 -an -vaapi_device /dev/dri/renderD128 -vf format=nv12,hwupload -c:v hevc_vaapi -b:v 6M -f null - 2>&1 | tr '\r' '\n' |
| OneXStation (8060S) | vaapi_h264 | 441 | 3 | 441 to 442 | 0.435 | distro ffmpeg (see inventory) | ffmpeg -hide_banner -benchmark -y -t 60 -i /var/tmp/bo-bench/assets/bbb-clip/bbb_1080p_60s.mp4 -an -vaapi_device /dev/dri/renderD128 -vf format=nv12,hwupload -c:v h264_vaapi -b:v 8M -f null - 2>&1 | tr '\r' '\n' |
| OneXStation (8060S) | vaapi_hevc | 755 | 3 | 754 to 757 | 1.6 | distro ffmpeg (see inventory) | ffmpeg -hide_banner -benchmark -y -t 60 -i /var/tmp/bo-bench/assets/bbb-clip/bbb_1080p_60s.mp4 -an -vaapi_device /dev/dri/renderD128 -vf format=nv12,hwupload -c:v hevc_vaapi -b:v 6M -f null - 2>&1 | tr '\r' '\n' |
For a homelab, Postgres favours the MS-02 Ultra: 4,789 transactions per second against 3,078, with 3.34 ms average latency against 5.20 ms. LAN throughput is level at 2.34 and 2.35 Gbit/s.
Local LLM
The Qwen3 30B-A3B result needs care. The OneXStation generates 92.0 tok/s and processes prompts at 2,261 tok/s on its GPU. The MS-02 Ultra figures for that model (14.4 and 290 tok/s) are CPU-only, because the model needs CPU offload on the 16 GB card and we did not run that by default. The 6.4x and 7.8x ratios compare a GPU with a CPU, which is the realistic choice on that machine but not like for like.
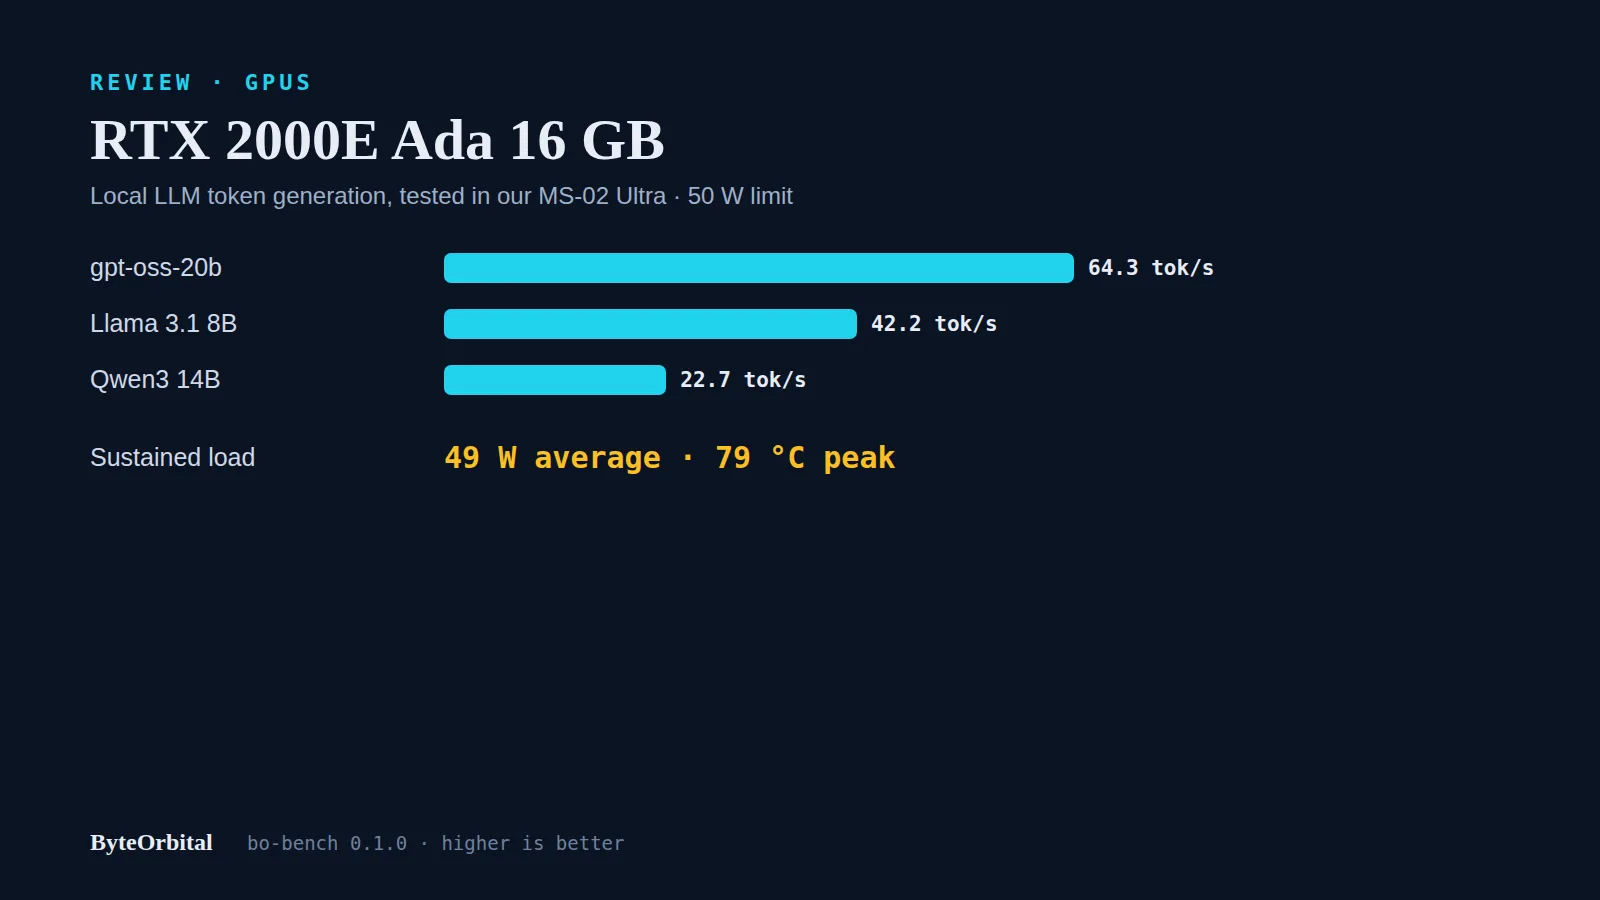
For models that fit both GPUs the picture is tighter. On gpt-oss-20b, generation is 79.4 tok/s on the OneXStation (ROCm), against 64.3 tok/s on the MS-02's card in its default configuration and 61.2 tok/s in the dedicated card run. Qwen3 14B is 25.6 against 22.7 tok/s. Prompt processing on small models goes to the MS-02's card: Llama 3.1 8B is 1,849 tok/s on CUDA against 1,495 tok/s on ROCm (1,772 on Vulkan), and Qwen3 14B is 954 against 808 tok/s (1,010 on Vulkan).
8060S ROCm runs gpt-oss-120b MXFP4; RTX 2000E Ada can't fit it
llama.cpp llama-bench. On gpt-oss-120b MXFP4: 8060S ROCm 56.3 vs 8060S Vulkan 53.9. · tokens per second · higher is better
+3.4% vs 8060S Vulkan 8060S ROCm leads in 6 of 6
View data table
| Series | Test | Value (tokens per second) | Runs | Min to max | Version | Command |
|---|---|---|---|---|---|---|
| 285HX CPU | Llama 3.1 8B Instruct Q4_K_M | 6.89 | 1 | 6.89 to 6.89 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | LD_LIBRARY_PATH=/opt/cuda-12.8/lib64:/opt/bo-bench/llama.cpp-b12300-cuda/bin /opt/bo-bench/llama.cpp-b12300-cuda/bin/llama-bench -ngl 0 -m /var/tmp/bo-bench/models/Meta-Llama-3.1-8B-Instruct-Q4_K_M.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| 285HX CPU | Qwen3 14B Q4_K_M | 3.64 | 1 | 3.64 to 3.64 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | LD_LIBRARY_PATH=/opt/cuda-12.8/lib64:/opt/bo-bench/llama.cpp-b12300-cuda/bin /opt/bo-bench/llama.cpp-b12300-cuda/bin/llama-bench -ngl 0 -m /var/tmp/bo-bench/models/Qwen3-14B-Q4_K_M.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| 285HX CPU | gpt-oss-20b MXFP4 | 9.11 | 1 | 9.11 to 9.11 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | LD_LIBRARY_PATH=/opt/cuda-12.8/lib64:/opt/bo-bench/llama.cpp-b12300-cuda/bin /opt/bo-bench/llama.cpp-b12300-cuda/bin/llama-bench -ngl 0 -m /var/tmp/bo-bench/models/gpt-oss-20b-MXFP4.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| 285HX CPU | Qwen3 30B-A3B Q4_K_M (MoE) | 14.4 | 1 | 14.4 to 14.4 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | LD_LIBRARY_PATH=/opt/cuda-12.8/lib64:/opt/bo-bench/llama.cpp-b12300-cuda/bin /opt/bo-bench/llama.cpp-b12300-cuda/bin/llama-bench -ngl 0 -m /var/tmp/bo-bench/models/Qwen3-30B-A3B-Q4_K_M.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| RTX 2000E Ada | Llama 3.1 8B Instruct Q4_K_M | 42.2 | 1 | 42.2 to 42.2 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | LD_LIBRARY_PATH=/opt/cuda-12.8/lib64:/opt/bo-bench/llama.cpp-b12300-cuda/bin /opt/bo-bench/llama.cpp-b12300-cuda/bin/llama-bench -fa 1 -m /var/tmp/bo-bench/models/Meta-Llama-3.1-8B-Instruct-Q4_K_M.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| RTX 2000E Ada | Qwen3 14B Q4_K_M | 22.7 | 1 | 22.7 to 22.7 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | LD_LIBRARY_PATH=/opt/cuda-12.8/lib64:/opt/bo-bench/llama.cpp-b12300-cuda/bin /opt/bo-bench/llama.cpp-b12300-cuda/bin/llama-bench -fa 1 -m /var/tmp/bo-bench/models/Qwen3-14B-Q4_K_M.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| RTX 2000E Ada | gpt-oss-20b MXFP4 | 64.3 | 1 | 64.3 to 64.3 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | LD_LIBRARY_PATH=/opt/cuda-12.8/lib64:/opt/bo-bench/llama.cpp-b12300-cuda/bin /opt/bo-bench/llama.cpp-b12300-cuda/bin/llama-bench -fa 1 -m /var/tmp/bo-bench/models/gpt-oss-20b-MXFP4.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| RTX 2000E Ada - ada_cuda | Llama 3.1 8B Instruct Q4_K_M | 42.3 | 1 | 42.3 to 42.3 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | LD_LIBRARY_PATH=/opt/cuda-12.8/lib64:/opt/bo-bench/llama.cpp-b12300-cuda/bin /opt/bo-bench/llama.cpp-b12300-cuda/bin/llama-bench -fa 1 -m /var/tmp/bo-bench/models/Meta-Llama-3.1-8B-Instruct-Q4_K_M.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| RTX 2000E Ada - ada_cuda | Qwen3 14B Q4_K_M | 19.2 | 1 | 19.2 to 19.2 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | LD_LIBRARY_PATH=/opt/cuda-12.8/lib64:/opt/bo-bench/llama.cpp-b12300-cuda/bin /opt/bo-bench/llama.cpp-b12300-cuda/bin/llama-bench -fa 1 -m /var/tmp/bo-bench/models/Qwen3-14B-Q4_K_M.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| RTX 2000E Ada - ada_cuda | gpt-oss-20b MXFP4 | 61.2 | 1 | 61.2 to 61.2 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | LD_LIBRARY_PATH=/opt/cuda-12.8/lib64:/opt/bo-bench/llama.cpp-b12300-cuda/bin /opt/bo-bench/llama.cpp-b12300-cuda/bin/llama-bench -fa 1 -m /var/tmp/bo-bench/models/gpt-oss-20b-MXFP4.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| Ryzen 395 CPU | Llama 3.1 8B Instruct Q4_K_M | 23.2 | 1 | 23.2 to 23.2 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | podman run --rm -v /srv/models:/models:ro docker.io/kyuz0/amd-strix-halo-toolboxes:vulkan-radv-performance_20261101T205203 llama-bench -ngl 0 -m /models/Meta-Llama-3.1-8B-Instruct-Q4_K_M.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| Ryzen 395 CPU | Qwen3 14B Q4_K_M | 12.8 | 1 | 12.8 to 12.8 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | podman run --rm -v /srv/models:/models:ro docker.io/kyuz0/amd-strix-halo-toolboxes:vulkan-radv-performance_20261101T205203 llama-bench -ngl 0 -m /models/Qwen3-14B-Q4_K_M.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| Ryzen 395 CPU | gpt-oss-20b MXFP4 | 40.2 | 1 | 40.2 to 40.2 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | podman run --rm -v /srv/models:/models:ro docker.io/kyuz0/amd-strix-halo-toolboxes:vulkan-radv-performance_20261101T205203 llama-bench -ngl 0 -m /models/gpt-oss-20b-MXFP4.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| Ryzen 395 CPU | Qwen3 30B-A3B Q4_K_M (MoE) | 42.9 | 1 | 42.9 to 42.9 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | podman run --rm -v /srv/models:/models:ro docker.io/kyuz0/amd-strix-halo-toolboxes:vulkan-radv-performance_20261101T205203 llama-bench -ngl 0 -m /models/Qwen3-30B-A3B-Q4_K_M.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| 8060S ROCm | Llama 3.1 8B Instruct Q4_K_M | 46.3 | 1 | 46.3 to 46.3 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | podman run --rm --device /dev/kfd --device /dev/dri --group-add keep-groups --security-opt seccomp=unconfined -v /srv/models:/models:ro docker.io/kyuz0/amd-strix-halo-toolboxes:rocm-10.0-strix-llama_20261102T063225 llama-bench -fa 1 -m /models/Meta-Llama-3.1-8B-Instruct-Q4_K_M.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| 8060S ROCm | Qwen3 14B Q4_K_M | 25.6 | 1 | 25.6 to 25.6 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | podman run --rm --device /dev/kfd --device /dev/dri --group-add keep-groups --security-opt seccomp=unconfined -v /srv/models:/models:ro docker.io/kyuz0/amd-strix-halo-toolboxes:rocm-10.0-strix-llama_20261102T063225 llama-bench -fa 1 -m /models/Qwen3-14B-Q4_K_M.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| 8060S ROCm | gpt-oss-20b MXFP4 | 79.4 | 1 | 79.4 to 79.4 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | podman run --rm --device /dev/kfd --device /dev/dri --group-add keep-groups --security-opt seccomp=unconfined -v /srv/models:/models:ro docker.io/kyuz0/amd-strix-halo-toolboxes:rocm-10.0-strix-llama_20261102T063225 llama-bench -fa 1 -m /models/gpt-oss-20b-MXFP4.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| 8060S ROCm | Qwen3 30B-A3B Q4_K_M (MoE) | 92 | 1 | 92 to 92 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | podman run --rm --device /dev/kfd --device /dev/dri --group-add keep-groups --security-opt seccomp=unconfined -v /srv/models:/models:ro docker.io/kyuz0/amd-strix-halo-toolboxes:rocm-10.0-strix-llama_20261102T063225 llama-bench -fa 1 -m /models/Qwen3-30B-A3B-Q4_K_M.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| 8060S ROCm | Llama 3.3 70B Instruct Q4_K_M | 5.31 | 1 | 5.31 to 5.31 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | podman run --rm --device /dev/kfd --device /dev/dri --group-add keep-groups --security-opt seccomp=unconfined -v /srv/models:/models:ro docker.io/kyuz0/amd-strix-halo-toolboxes:rocm-10.0-strix-llama_20261102T063225 llama-bench -fa 1 -m /models/Llama-3.3-70B-Instruct-Q4_K_M.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| 8060S ROCm | gpt-oss-120b MXFP4 | 56.3 | 1 | 56.3 to 56.3 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | podman run --rm --device /dev/kfd --device /dev/dri --group-add keep-groups --security-opt seccomp=unconfined -v /srv/models:/models:ro docker.io/kyuz0/amd-strix-halo-toolboxes:rocm-10.0-strix-llama_20261102T063225 llama-bench -fa 1 -m /models/gpt-oss-120b/gpt-oss-120b-MXFP4.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| 8060S Vulkan | Llama 3.1 8B Instruct Q4_K_M | 44.6 | 1 | 44.6 to 44.6 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | podman run --rm --device /dev/dri --group-add keep-groups --security-opt seccomp=unconfined -v /srv/models:/models:ro docker.io/kyuz0/amd-strix-halo-toolboxes:vulkan-radv-performance_20261101T205203 llama-bench -fa 1 -m /models/Meta-Llama-3.1-8B-Instruct-Q4_K_M.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| 8060S Vulkan | Qwen3 14B Q4_K_M | 24.8 | 1 | 24.8 to 24.8 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | podman run --rm --device /dev/dri --group-add keep-groups --security-opt seccomp=unconfined -v /srv/models:/models:ro docker.io/kyuz0/amd-strix-halo-toolboxes:vulkan-radv-performance_20261101T205203 llama-bench -fa 1 -m /models/Qwen3-14B-Q4_K_M.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| 8060S Vulkan | gpt-oss-20b MXFP4 | 75.9 | 1 | 75.9 to 75.9 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | podman run --rm --device /dev/dri --group-add keep-groups --security-opt seccomp=unconfined -v /srv/models:/models:ro docker.io/kyuz0/amd-strix-halo-toolboxes:vulkan-radv-performance_20261101T205203 llama-bench -fa 1 -m /models/gpt-oss-20b-MXFP4.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| 8060S Vulkan | Qwen3 30B-A3B Q4_K_M (MoE) | 91.1 | 1 | 91.1 to 91.1 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | podman run --rm --device /dev/dri --group-add keep-groups --security-opt seccomp=unconfined -v /srv/models:/models:ro docker.io/kyuz0/amd-strix-halo-toolboxes:vulkan-radv-performance_20261101T205203 llama-bench -fa 1 -m /models/Qwen3-30B-A3B-Q4_K_M.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| 8060S Vulkan | Llama 3.3 70B Instruct Q4_K_M | 5.28 | 1 | 5.28 to 5.28 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | podman run --rm --device /dev/dri --group-add keep-groups --security-opt seccomp=unconfined -v /srv/models:/models:ro docker.io/kyuz0/amd-strix-halo-toolboxes:vulkan-radv-performance_20261101T205203 llama-bench -fa 1 -m /models/Llama-3.3-70B-Instruct-Q4_K_M.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| 8060S Vulkan | gpt-oss-120b MXFP4 | 53.9 | 1 | 53.9 to 53.9 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | podman run --rm --device /dev/dri --group-add keep-groups --security-opt seccomp=unconfined -v /srv/models:/models:ro docker.io/kyuz0/amd-strix-halo-toolboxes:vulkan-radv-performance_20261101T205203 llama-bench -fa 1 -m /models/gpt-oss-120b/gpt-oss-120b-MXFP4.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
Series with no bar for a model could not fit it (see what_fits in findings.json).
Big models are the OneXStation's territory: gpt-oss-120b generates at 56.3 tok/s, and Llama 3.3 70B at 5.31 tok/s with 152 tok/s of prompt processing. Context length costs speed. With 32k of context, Qwen3 30B-A3B on the OneXStation's ROCm backend still generates 39.1 tok/s.
Efficiency is closer than a headline figure suggests once you compare like for like at the wall. Llama 3.1 8B generation is 0.393 tok/s per watt on ROCm (0.402 on Vulkan) against 0.396 for the MS-02's card, which is level. On gpt-oss-20b it is 0.727 against 0.633. The OneXStation's real efficiency advantage shows on the larger models only it can run.
OneXStation (8060S) wins every tokens per watt test, by 2-558%
Generation speed divided by average wall power over the test. · tokens/s per watt · higher is better
+14% vs 8060S Vulkan 8060S ROCm leads in 3 of 6
View data table
| Series | Test | Value (tokens/s per watt) |
|---|---|---|
| 285HX CPU | Llama 3.1 8B Instruct Q4_K_M | 0.077 |
| 285HX CPU | Qwen3 14B Q4_K_M | 0.038 |
| 285HX CPU | gpt-oss-20b MXFP4 | 0.09 |
| 285HX CPU | Qwen3 30B-A3B Q4_K_M (MoE) | 0.133 |
| RTX 2000E Ada | Llama 3.1 8B Instruct Q4_K_M | 0.387 |
| RTX 2000E Ada | Qwen3 14B Q4_K_M | 0.194 |
| RTX 2000E Ada | gpt-oss-20b MXFP4 | 0.437 |
| RTX 2000E Ada - ada_cuda | Llama 3.1 8B Instruct Q4_K_M | 0.396 |
| RTX 2000E Ada - ada_cuda | Qwen3 14B Q4_K_M | 0.186 |
| RTX 2000E Ada - ada_cuda | gpt-oss-20b MXFP4 | 0.633 |
| 8060S ROCm | Llama 3.1 8B Instruct Q4_K_M | 0.393 |
| 8060S ROCm | Qwen3 14B Q4_K_M | 0.215 |
| 8060S ROCm | gpt-oss-20b MXFP4 | 0.727 |
| 8060S ROCm | Qwen3 30B-A3B Q4_K_M (MoE) | 0.77 |
| 8060S ROCm | Llama 3.3 70B Instruct Q4_K_M | 0.043 |
| 8060S ROCm | gpt-oss-120b MXFP4 | 0.531 |
| 8060S Vulkan | Llama 3.1 8B Instruct Q4_K_M | 0.402 |
| 8060S Vulkan | Qwen3 14B Q4_K_M | 0.203 |
| 8060S Vulkan | gpt-oss-20b MXFP4 | 0.612 |
| 8060S Vulkan | Qwen3 30B-A3B Q4_K_M (MoE) | 0.875 |
| 8060S Vulkan | Llama 3.3 70B Instruct Q4_K_M | 0.043 |
| 8060S Vulkan | gpt-oss-120b MXFP4 | 0.467 |
| Ryzen 395 CPU | Llama 3.1 8B Instruct Q4_K_M | 0.203 |
| Ryzen 395 CPU | Qwen3 14B Q4_K_M | 0.11 |
| Ryzen 395 CPU | gpt-oss-20b MXFP4 | 0.336 |
| Ryzen 395 CPU | Qwen3 30B-A3B Q4_K_M (MoE) | 0.354 |
Average power covers the whole test window including model load: compare across machines, not as a spec.
On thermals, we have temperature data only for the RTX card, which peaked at 79 °C in a sustained run. We have no comparable temperature series for the OneXStation.
What fits where
| Llama 3.1 8B Instruct Q4_K_M (4.9 GB) | OneXStation: yes; MS-02 Ultra: yes (CUDA) |
|---|---|
| Qwen3 14B Q4_K_M (9.0 GB) | OneXStation: yes; MS-02 Ultra: yes (CUDA) |
| gpt-oss-20b MXFP4 (12.1 GB) | OneXStation: yes; MS-02 Ultra: yes (CUDA) |
| Qwen3 30B-A3B Q4_K_M (18.6 GB) | OneXStation: yes; MS-02 Ultra: needs CPU offload |
| gpt-oss-120b MXFP4 (63.4 GB) | OneXStation: yes; MS-02 Ultra: no (CPU offload only) |
| Llama 3.3 70B Q4_K_M (42.5 GB) | OneXStation: yes; MS-02 Ultra: no (CPU offload only) |
Who should buy which
We apply fixed rules: a gap of 15% or more is a clear win, and smaller gaps are judgement calls.
- Big models (30B to 120B class) fully on the GPU: the OneXStation. It holds models up to 63 GB; the MS-02 Ultra's card tops out at 12 GB.
- Fast chat with small models (up to about 15B): a close call. The OneXStation leads by 9% on Llama 3.1 8B (46.3 vs 42.3 tok/s). Our judgement is to decide on price, noise and size, which we did not measure.
- Long prompts, RAG and coding agents: a simple rule picks the OneXStation (2,261 vs 290 tok/s on Qwen3 30B-A3B), but that compares its GPU with the MS-02's CPU. On models the MS-02's card holds, the card is as quick or quicker at prompt processing.
- CPU-heavy work such as archiving: the OneXStation on 7-Zip, though the MS-02 wins all-thread sysbench and Postgres. Our judgement is to pick on your own workload.
- Hardware video transcoding: the OneXStation, at 755 fps against 451 fps.
The MS-02 Ultra has one thing the numbers do not capture: its RTX card can be swapped, so the GPU half of this comparison is not fixed. Its memory also ran below its rating, which may change CPU-side results. Price, noise, size, warranty and availability were not measured.
Verdict
If local AI is the main job, buy the OneXStation: it runs models the MS-02 Ultra's 16 GB card cannot hold. Choose the MS-02 Ultra if you want a conventional x86 workstation with a replaceable GPU, strong all-thread CPU throughput and Postgres speed, and mostly run models under about 15B.
Some links below may earn us a commission at no cost to you. See our affiliate disclosure.
What we left out
We did not measure price, noise, size or warranty, and we did not test the MS-02 Ultra at its rated memory speed.