Benchmarks run by ByteOrbital on our own hardware; written with AI assistance from our results.
The RTX 2000E Ada Generation is a workstation card with 16 GB of memory, a 50 W power limit and a low-profile form factor. That makes it one of the few discrete GPUs that fits a compact machine such as our Minisforum MS-02 Ultra. We own the machine and the card, use them daily, and ran our benchmark suite with the card as the main accelerator. The question is simple: how much local AI does 50 W and 16 GB actually buy?
Prefer to watch? Nova and Dex walk through every result in our five-minute video on YouTube.
How we tested
What fits in 16 GB
Memory decides what a card can do before speed does, so start there.
| Llama 3.1 8B Instruct Q4_K_M (4.9 GB) | Fits on the card |
|---|---|
| Qwen3 14B Q4_K_M (9.0 GB) | Fits on the card |
| gpt-oss-20b MXFP4 (12.1 GB) | Fits on the card |
| Qwen3 30B-A3B Q4_K_M (18.6 GB) | Needs CPU offload (not run by default) |
| Llama 3.3 70B Instruct Q4_K_M (42.5 GB) | Does not fit |
| gpt-oss-120b MXFP4 (63.4 GB) | Does not fit |
The card's memory is 16,380 MiB. In practice, a model of about 12 GB leaves modest room for context, and the 18.6 GB mixture-of-experts model is already out of reach without offloading to the CPU. For comparison, the Ryzen AI Max+ 395 machine in our other tests holds all six, including the 63.4 GB model, because it shares a large memory pool.
8060S ROCm runs gpt-oss-120b MXFP4; RTX 2000E Ada can't fit it
llama.cpp llama-bench. On gpt-oss-120b MXFP4: 8060S ROCm 56.3 vs 8060S Vulkan 53.9. · tokens per second · higher is better
+3.4% vs 8060S Vulkan 8060S ROCm leads in 6 of 6
View data table
| Series | Test | Value (tokens per second) | Runs | Min to max | Version | Command |
|---|---|---|---|---|---|---|
| 285HX CPU | Llama 3.1 8B Instruct Q4_K_M | 6.89 | 1 | 6.89 to 6.89 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | LD_LIBRARY_PATH=/opt/cuda-12.8/lib64:/opt/bo-bench/llama.cpp-b12300-cuda/bin /opt/bo-bench/llama.cpp-b12300-cuda/bin/llama-bench -ngl 0 -m /var/tmp/bo-bench/models/Meta-Llama-3.1-8B-Instruct-Q4_K_M.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| 285HX CPU | Qwen3 14B Q4_K_M | 3.64 | 1 | 3.64 to 3.64 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | LD_LIBRARY_PATH=/opt/cuda-12.8/lib64:/opt/bo-bench/llama.cpp-b12300-cuda/bin /opt/bo-bench/llama.cpp-b12300-cuda/bin/llama-bench -ngl 0 -m /var/tmp/bo-bench/models/Qwen3-14B-Q4_K_M.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| 285HX CPU | gpt-oss-20b MXFP4 | 9.11 | 1 | 9.11 to 9.11 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | LD_LIBRARY_PATH=/opt/cuda-12.8/lib64:/opt/bo-bench/llama.cpp-b12300-cuda/bin /opt/bo-bench/llama.cpp-b12300-cuda/bin/llama-bench -ngl 0 -m /var/tmp/bo-bench/models/gpt-oss-20b-MXFP4.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| 285HX CPU | Qwen3 30B-A3B Q4_K_M (MoE) | 14.4 | 1 | 14.4 to 14.4 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | LD_LIBRARY_PATH=/opt/cuda-12.8/lib64:/opt/bo-bench/llama.cpp-b12300-cuda/bin /opt/bo-bench/llama.cpp-b12300-cuda/bin/llama-bench -ngl 0 -m /var/tmp/bo-bench/models/Qwen3-30B-A3B-Q4_K_M.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| RTX 2000E Ada | Llama 3.1 8B Instruct Q4_K_M | 42.2 | 1 | 42.2 to 42.2 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | LD_LIBRARY_PATH=/opt/cuda-12.8/lib64:/opt/bo-bench/llama.cpp-b12300-cuda/bin /opt/bo-bench/llama.cpp-b12300-cuda/bin/llama-bench -fa 1 -m /var/tmp/bo-bench/models/Meta-Llama-3.1-8B-Instruct-Q4_K_M.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| RTX 2000E Ada | Qwen3 14B Q4_K_M | 22.7 | 1 | 22.7 to 22.7 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | LD_LIBRARY_PATH=/opt/cuda-12.8/lib64:/opt/bo-bench/llama.cpp-b12300-cuda/bin /opt/bo-bench/llama.cpp-b12300-cuda/bin/llama-bench -fa 1 -m /var/tmp/bo-bench/models/Qwen3-14B-Q4_K_M.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| RTX 2000E Ada | gpt-oss-20b MXFP4 | 64.3 | 1 | 64.3 to 64.3 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | LD_LIBRARY_PATH=/opt/cuda-12.8/lib64:/opt/bo-bench/llama.cpp-b12300-cuda/bin /opt/bo-bench/llama.cpp-b12300-cuda/bin/llama-bench -fa 1 -m /var/tmp/bo-bench/models/gpt-oss-20b-MXFP4.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| RTX 2000E Ada - ada_cuda | Llama 3.1 8B Instruct Q4_K_M | 42.3 | 1 | 42.3 to 42.3 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | LD_LIBRARY_PATH=/opt/cuda-12.8/lib64:/opt/bo-bench/llama.cpp-b12300-cuda/bin /opt/bo-bench/llama.cpp-b12300-cuda/bin/llama-bench -fa 1 -m /var/tmp/bo-bench/models/Meta-Llama-3.1-8B-Instruct-Q4_K_M.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| RTX 2000E Ada - ada_cuda | Qwen3 14B Q4_K_M | 19.2 | 1 | 19.2 to 19.2 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | LD_LIBRARY_PATH=/opt/cuda-12.8/lib64:/opt/bo-bench/llama.cpp-b12300-cuda/bin /opt/bo-bench/llama.cpp-b12300-cuda/bin/llama-bench -fa 1 -m /var/tmp/bo-bench/models/Qwen3-14B-Q4_K_M.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| RTX 2000E Ada - ada_cuda | gpt-oss-20b MXFP4 | 61.2 | 1 | 61.2 to 61.2 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | LD_LIBRARY_PATH=/opt/cuda-12.8/lib64:/opt/bo-bench/llama.cpp-b12300-cuda/bin /opt/bo-bench/llama.cpp-b12300-cuda/bin/llama-bench -fa 1 -m /var/tmp/bo-bench/models/gpt-oss-20b-MXFP4.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| Ryzen 395 CPU | Llama 3.1 8B Instruct Q4_K_M | 23.2 | 1 | 23.2 to 23.2 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | podman run --rm -v /srv/models:/models:ro docker.io/kyuz0/amd-strix-halo-toolboxes:vulkan-radv-performance_20261101T205203 llama-bench -ngl 0 -m /models/Meta-Llama-3.1-8B-Instruct-Q4_K_M.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| Ryzen 395 CPU | Qwen3 14B Q4_K_M | 12.8 | 1 | 12.8 to 12.8 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | podman run --rm -v /srv/models:/models:ro docker.io/kyuz0/amd-strix-halo-toolboxes:vulkan-radv-performance_20261101T205203 llama-bench -ngl 0 -m /models/Qwen3-14B-Q4_K_M.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| Ryzen 395 CPU | gpt-oss-20b MXFP4 | 40.2 | 1 | 40.2 to 40.2 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | podman run --rm -v /srv/models:/models:ro docker.io/kyuz0/amd-strix-halo-toolboxes:vulkan-radv-performance_20261101T205203 llama-bench -ngl 0 -m /models/gpt-oss-20b-MXFP4.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| Ryzen 395 CPU | Qwen3 30B-A3B Q4_K_M (MoE) | 42.9 | 1 | 42.9 to 42.9 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | podman run --rm -v /srv/models:/models:ro docker.io/kyuz0/amd-strix-halo-toolboxes:vulkan-radv-performance_20261101T205203 llama-bench -ngl 0 -m /models/Qwen3-30B-A3B-Q4_K_M.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
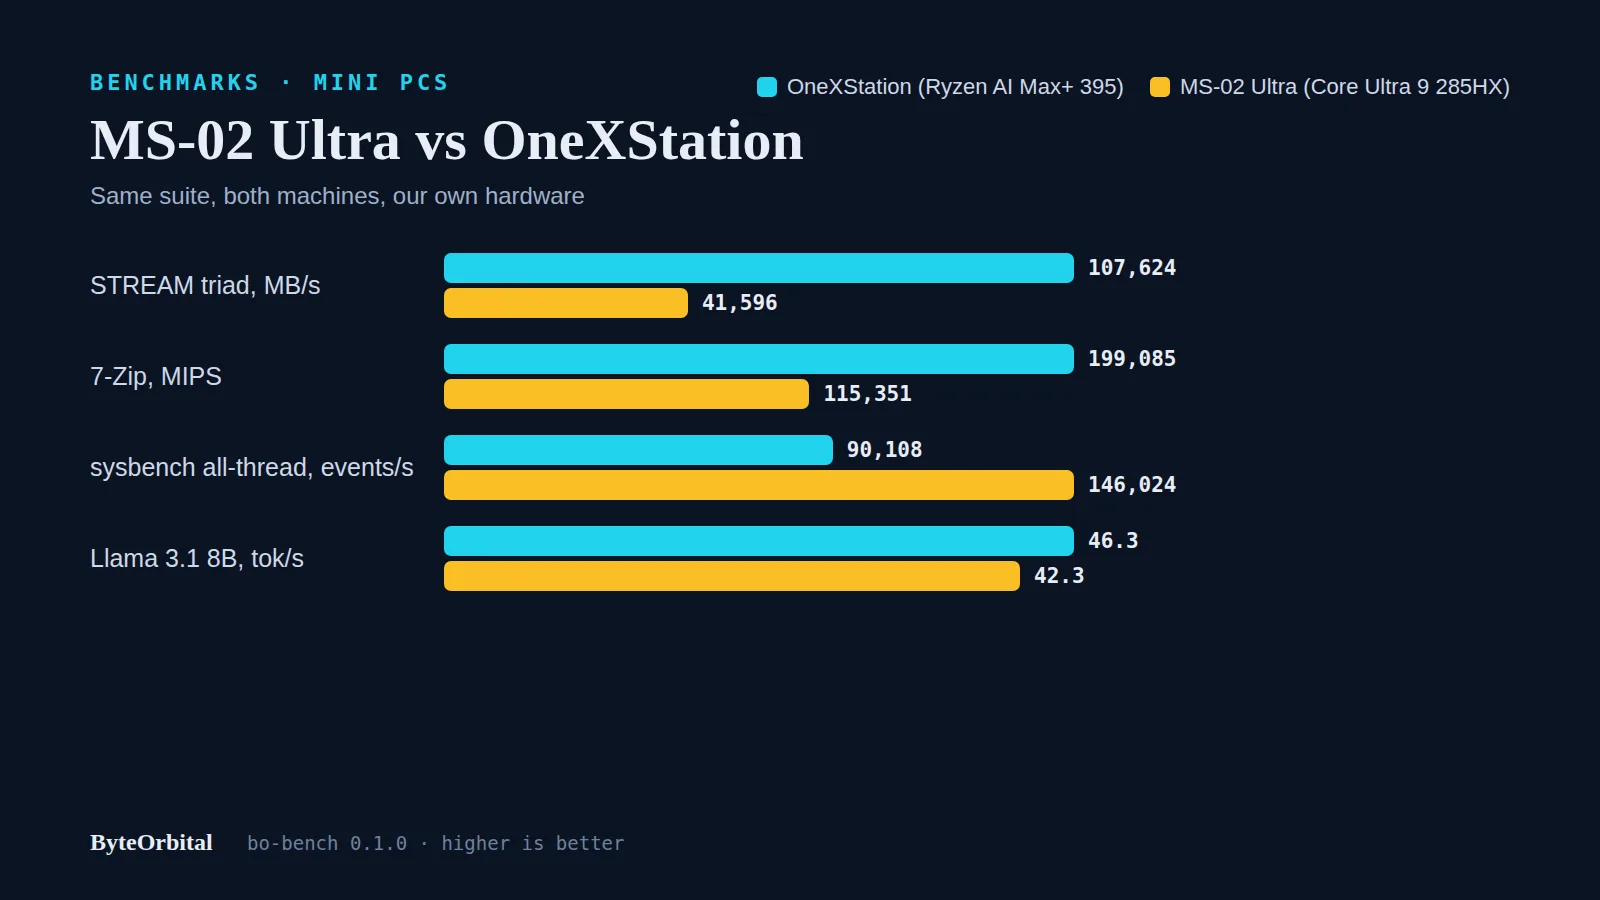
| 8060S ROCm | Llama 3.1 8B Instruct Q4_K_M | 46.3 | 1 | 46.3 to 46.3 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | podman run --rm --device /dev/kfd --device /dev/dri --group-add keep-groups --security-opt seccomp=unconfined -v /srv/models:/models:ro docker.io/kyuz0/amd-strix-halo-toolboxes:rocm-10.0-strix-llama_20261102T063225 llama-bench -fa 1 -m /models/Meta-Llama-3.1-8B-Instruct-Q4_K_M.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| 8060S ROCm | Qwen3 14B Q4_K_M | 25.6 | 1 | 25.6 to 25.6 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | podman run --rm --device /dev/kfd --device /dev/dri --group-add keep-groups --security-opt seccomp=unconfined -v /srv/models:/models:ro docker.io/kyuz0/amd-strix-halo-toolboxes:rocm-10.0-strix-llama_20261102T063225 llama-bench -fa 1 -m /models/Qwen3-14B-Q4_K_M.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| 8060S ROCm | gpt-oss-20b MXFP4 | 79.4 | 1 | 79.4 to 79.4 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | podman run --rm --device /dev/kfd --device /dev/dri --group-add keep-groups --security-opt seccomp=unconfined -v /srv/models:/models:ro docker.io/kyuz0/amd-strix-halo-toolboxes:rocm-10.0-strix-llama_20261102T063225 llama-bench -fa 1 -m /models/gpt-oss-20b-MXFP4.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| 8060S ROCm | Qwen3 30B-A3B Q4_K_M (MoE) | 92 | 1 | 92 to 92 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | podman run --rm --device /dev/kfd --device /dev/dri --group-add keep-groups --security-opt seccomp=unconfined -v /srv/models:/models:ro docker.io/kyuz0/amd-strix-halo-toolboxes:rocm-10.0-strix-llama_20261102T063225 llama-bench -fa 1 -m /models/Qwen3-30B-A3B-Q4_K_M.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| 8060S ROCm | Llama 3.3 70B Instruct Q4_K_M | 5.31 | 1 | 5.31 to 5.31 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | podman run --rm --device /dev/kfd --device /dev/dri --group-add keep-groups --security-opt seccomp=unconfined -v /srv/models:/models:ro docker.io/kyuz0/amd-strix-halo-toolboxes:rocm-10.0-strix-llama_20261102T063225 llama-bench -fa 1 -m /models/Llama-3.3-70B-Instruct-Q4_K_M.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| 8060S ROCm | gpt-oss-120b MXFP4 | 56.3 | 1 | 56.3 to 56.3 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | podman run --rm --device /dev/kfd --device /dev/dri --group-add keep-groups --security-opt seccomp=unconfined -v /srv/models:/models:ro docker.io/kyuz0/amd-strix-halo-toolboxes:rocm-10.0-strix-llama_20261102T063225 llama-bench -fa 1 -m /models/gpt-oss-120b/gpt-oss-120b-MXFP4.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| 8060S Vulkan | Llama 3.1 8B Instruct Q4_K_M | 44.6 | 1 | 44.6 to 44.6 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | podman run --rm --device /dev/dri --group-add keep-groups --security-opt seccomp=unconfined -v /srv/models:/models:ro docker.io/kyuz0/amd-strix-halo-toolboxes:vulkan-radv-performance_20261101T205203 llama-bench -fa 1 -m /models/Meta-Llama-3.1-8B-Instruct-Q4_K_M.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| 8060S Vulkan | Qwen3 14B Q4_K_M | 24.8 | 1 | 24.8 to 24.8 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | podman run --rm --device /dev/dri --group-add keep-groups --security-opt seccomp=unconfined -v /srv/models:/models:ro docker.io/kyuz0/amd-strix-halo-toolboxes:vulkan-radv-performance_20261101T205203 llama-bench -fa 1 -m /models/Qwen3-14B-Q4_K_M.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| 8060S Vulkan | gpt-oss-20b MXFP4 | 75.9 | 1 | 75.9 to 75.9 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | podman run --rm --device /dev/dri --group-add keep-groups --security-opt seccomp=unconfined -v /srv/models:/models:ro docker.io/kyuz0/amd-strix-halo-toolboxes:vulkan-radv-performance_20261101T205203 llama-bench -fa 1 -m /models/gpt-oss-20b-MXFP4.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| 8060S Vulkan | Qwen3 30B-A3B Q4_K_M (MoE) | 91.1 | 1 | 91.1 to 91.1 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | podman run --rm --device /dev/dri --group-add keep-groups --security-opt seccomp=unconfined -v /srv/models:/models:ro docker.io/kyuz0/amd-strix-halo-toolboxes:vulkan-radv-performance_20261101T205203 llama-bench -fa 1 -m /models/Qwen3-30B-A3B-Q4_K_M.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| 8060S Vulkan | Llama 3.3 70B Instruct Q4_K_M | 5.28 | 1 | 5.28 to 5.28 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | podman run --rm --device /dev/dri --group-add keep-groups --security-opt seccomp=unconfined -v /srv/models:/models:ro docker.io/kyuz0/amd-strix-halo-toolboxes:vulkan-radv-performance_20261101T205203 llama-bench -fa 1 -m /models/Llama-3.3-70B-Instruct-Q4_K_M.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
| 8060S Vulkan | gpt-oss-120b MXFP4 | 53.9 | 1 | 53.9 to 53.9 | llama.cpp b12300 (ms01 CUDA build, sm_89); ms03 kyuz0 toolbox images pinned in hosts.yaml (~b12297) | podman run --rm --device /dev/dri --group-add keep-groups --security-opt seccomp=unconfined -v /srv/models:/models:ro docker.io/kyuz0/amd-strix-halo-toolboxes:vulkan-radv-performance_20261101T205203 llama-bench -fa 1 -m /models/gpt-oss-120b/gpt-oss-120b-MXFP4.gguf -p 512 -n 128 -d 0,4096,16384,32768 -r 3 -o json 2>/var/tmp/bo-bench/llama.err || { tail -5 /var/tmp/bo-bench/llama.err; exit 1; } |
Series with no bar for a model could not fit it (see what_fits in findings.json).
Local LLM speed
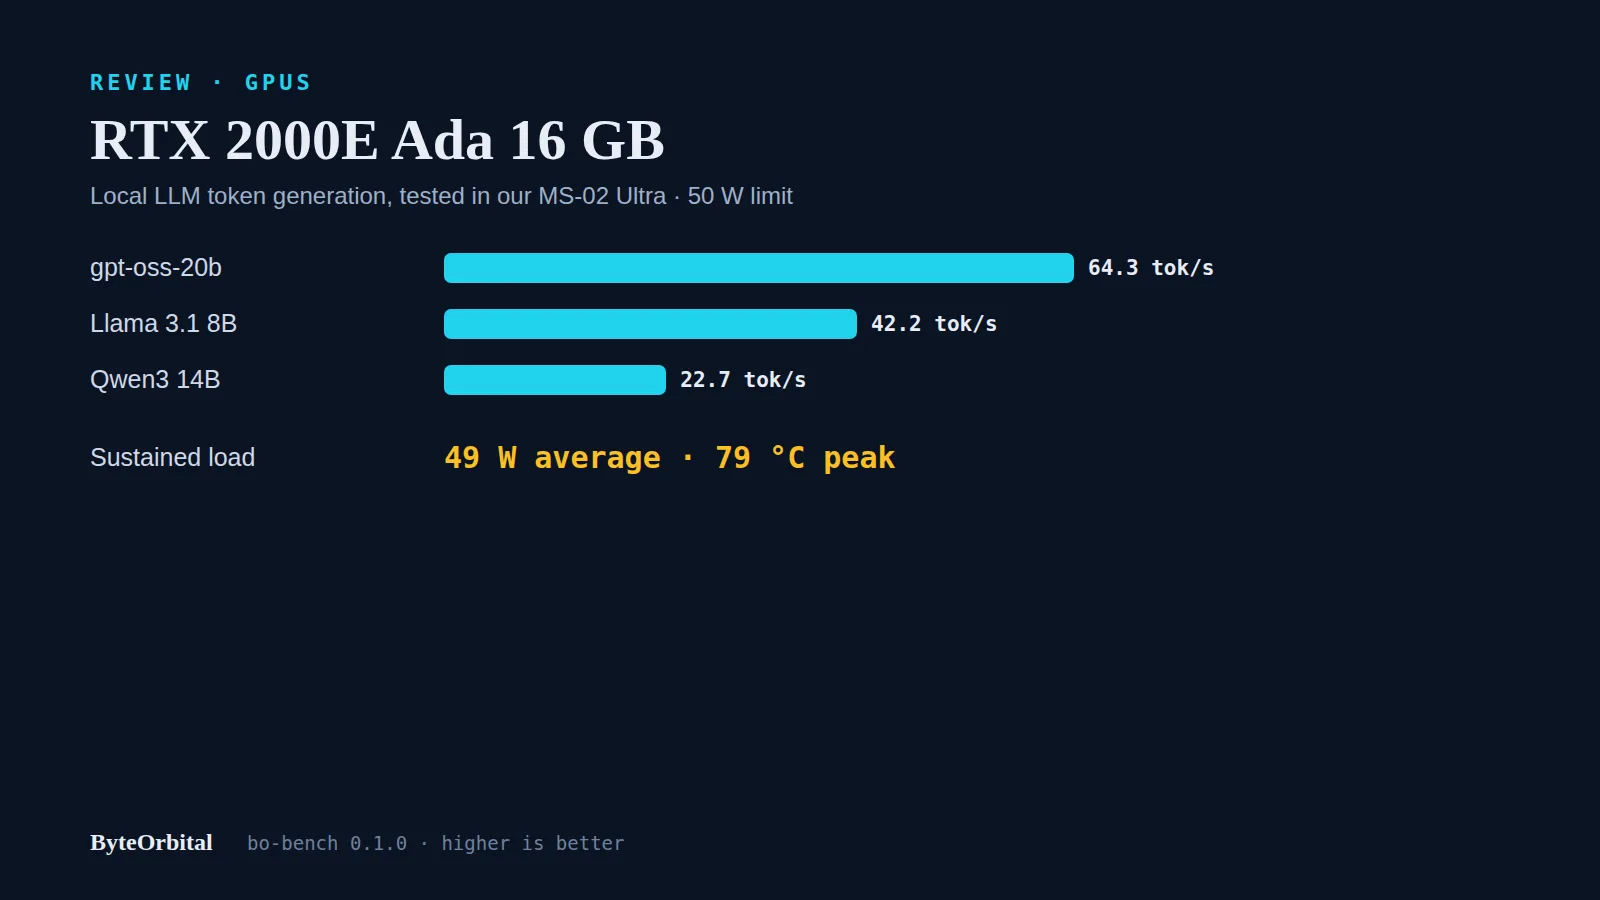
Here are the llama.cpp results with the card, from the default run and the dedicated ada_cuda run.
| Llama 3.1 8B generation | 42.2 tok/s (default), 42.3 tok/s (ada_cuda) |
|---|---|
| Llama 3.1 8B prompt processing | 1,849 tok/s (default), 1,852 tok/s (ada_cuda) |
| Qwen3 14B generation | 22.7 tok/s (default), 19.2 tok/s (ada_cuda) |
| Qwen3 14B prompt processing | 954 tok/s (default), 898 tok/s (ada_cuda) |
| gpt-oss-20b generation | 64.3 tok/s (default), 61.2 tok/s (ada_cuda) |
| gpt-oss-20b prompt processing | 1,625 tok/s (default), 1,957 tok/s (ada_cuda) |
Do not read too much into the gaps between those two columns. Both runs used the same card, so any difference is run-to-run variation plus whatever else the machine was doing. The two configurations disagreed by +20% on gpt-oss-20b prompt processing and by -15% on Qwen3 14B generation, and the Llama 3.1 8B results matched to within 1%. Each is a single run. Treat the card as roughly 40 tok/s on an 8B model, 20 on a 14B and 60 on gpt-oss-20b.
Context length costs speed. At 32k of context, gpt-oss-20b generation falls from 64.3 to 51.1 tok/s on the default run, and Llama 3.1 8B falls from 42.2 to 17.6 tok/s. Prompt processing on gpt-oss-20b drops from 1,625 to 1,029 tok/s over the same range.
Against the CPU in the same machine the card is the difference between usable and not. The Core Ultra 9 285HX manages 6.89 tok/s on Llama 3.1 8B, 3.64 on Qwen3 14B and 9.11 on gpt-oss-20b, against 42.2, 22.7 and 64.3 tok/s on the card.
Speech, rendering and video
Whisper large-v3-turbo transcribes at 15.2x real time on CUDA in the default run and 16.0x in the ada_cuda run, against 2.68x and 2.71x on the CPU. The Ryzen AI Max+ 395 machine's CPU alone reaches 3.78x, so the card's gain over any CPU here is large.
In Blender, the BMW scene renders in 26.9 s on CUDA and 27.1 s in the ada_cuda run, which is level. With OptiX it takes 13.0 s, so use OptiX if your renderer supports it.
MS-02 Ultra and MS-02 Ultra - ada_cuda are level on Blender GPU rendering (bmw27)
bo-bench blender gpu. · s · lower is better
+0.6% vs MS-02 Ultra - ada_cuda MS-02 Ultra leads in 1 of 2
View data table
| Series | Test | Value (s) | Runs | Min to max | Std dev | Version | Command |
|---|---|---|---|---|---|---|---|
| MS-02 Ultra | cuda | 26.9 | 2 | 26.9 to 27 | 0.078 | Blender 5.2.4; scenes bmw27 / classroom / monster | for s in bmw27 classroom monster; do t=$(/opt/bo-bench/blender-5.2.4-linux-x64/blender -b /var/tmp/bo-bench/assets/scene-$s/$s/main.blend -noaudio -o /var/tmp/bo-bench/bout/f_#### -E CYCLES --python /var/tmp/bo-bench/blender_dev.py -f 1 -- CUDA 2>&1 | grep -oE 'Time: [0-9]+:[0-9.]+ \(Saving' | tail -1 | sed -E 's/Time: ([0-9]+):([0-9.]+).*/\1 \2/' | awk '{print $1*60+$2}') echo "BO_SCENE $s $t" done |
| MS-02 Ultra - ada_cuda | cuda | 27.1 | 2 | 27 to 27.2 | 0.149 | Blender 5.2.4; scenes bmw27 / classroom / monster | for s in bmw27 classroom monster; do t=$(/opt/bo-bench/blender-5.2.4-linux-x64/blender -b /var/tmp/bo-bench/assets/scene-$s/$s/main.blend -noaudio -o /var/tmp/bo-bench/bout/f_#### -E CYCLES --python /var/tmp/bo-bench/blender_dev.py -f 1 -- CUDA 2>&1 | grep -oE 'Time: [0-9]+:[0-9.]+ \(Saving' | tail -1 | sed -E 's/Time: ([0-9]+):([0-9.]+).*/\1 \2/' | awk '{print $1*60+$2}') echo "BO_SCENE $s $t" done |
| MS-02 Ultra - ada_cuda | optix | 13 | 2 | 12.9 to 13 | 0.064 | Blender 5.2.4; scenes bmw27 / classroom / monster | for s in bmw27 classroom monster; do t=$(/opt/bo-bench/blender-5.2.4-linux-x64/blender -b /var/tmp/bo-bench/assets/scene-$s/$s/main.blend -noaudio -o /var/tmp/bo-bench/bout/f_#### -E CYCLES --python /var/tmp/bo-bench/blender_dev.py -f 1 -- OPTIX 2>&1 | grep -oE 'Time: [0-9]+:[0-9.]+ \(Saving' | tail -1 | sed -E 's/Time: ([0-9]+):([0-9.]+).*/\1 \2/' | awk '{print $1*60+$2}') echo "BO_SCENE $s $t" done |
For video encoding, NVENC does 371 fps for HEVC, 322 fps for H.264 and 393 fps for AV1 on our 1080p test clip. The surprise is the Intel iGPU in the same machine: its VAAPI encoder does 451 fps for HEVC and 414 fps for H.264 in the ada_cuda configuration, and 427 and 400 fps in the igpu_arc one. If you only need H.264 or HEVC, you do not need this card for encoding. AV1 is the reason to use NVENC here. For scale, the OneXStation's VAAPI HEVC encoder reaches 755 fps.
OneXStation (8060S) tops hardware video encoding: 755 fps (vaapi_hevc)
Big Buck Bunny 1080p, 60 s source. · fps · higher is better
+4.6% vs MS-02 Ultra - igpu_arc MS-02 Ultra - ada_cuda leads in 2 of 7
View data table
| Series | Test | Value (fps) | Runs | Min to max | Std dev | Version | Command |
|---|---|---|---|---|---|---|---|
| MS-02 Ultra | nvenc_hevc | 371 | 3 | 368 to 371 | 1.97 | distro ffmpeg (see inventory) | ffmpeg -hide_banner -benchmark -y -t 60 -i /var/tmp/bo-bench/assets/bbb-clip/bbb_1080p_60s.mp4 -an -c:v hevc_nvenc -preset p5 -b:v 6M -f null - 2>&1 | tr '\r' '\n' |
| MS-02 Ultra | intel_vaapi_h264 | 389 | 3 | 387 to 401 | 7.69 | distro ffmpeg (see inventory) | ffmpeg -hide_banner -benchmark -y -t 60 -i /var/tmp/bo-bench/assets/bbb-clip/bbb_1080p_60s.mp4 -an -vaapi_device /dev/dri/renderD128 -vf format=nv12,hwupload -c:v h264_vaapi -b:v 8M -f null - 2>&1 | tr '\r' '\n' |
| MS-02 Ultra | intel_vaapi_hevc | 405 | 3 | 397 to 424 | 13.6 | distro ffmpeg (see inventory) | ffmpeg -hide_banner -benchmark -y -t 60 -i /var/tmp/bo-bench/assets/bbb-clip/bbb_1080p_60s.mp4 -an -vaapi_device /dev/dri/renderD128 -vf format=nv12,hwupload -c:v hevc_vaapi -b:v 6M -f null - 2>&1 | tr '\r' '\n' |
| MS-02 Ultra - ada_cuda | nvenc_hevc | 371 | 3 | 369 to 371 | 1.51 | distro ffmpeg (see inventory) | ffmpeg -hide_banner -benchmark -y -t 60 -i /var/tmp/bo-bench/assets/bbb-clip/bbb_1080p_60s.mp4 -an -c:v hevc_nvenc -preset p5 -b:v 6M -f null - 2>&1 | tr '\r' '\n' |
| MS-02 Ultra - ada_cuda | intel_vaapi_h264 | 414 | 3 | 409 to 425 | 8.19 | distro ffmpeg (see inventory) | ffmpeg -hide_banner -benchmark -y -t 60 -i /var/tmp/bo-bench/assets/bbb-clip/bbb_1080p_60s.mp4 -an -vaapi_device /dev/dri/renderD128 -vf format=nv12,hwupload -c:v h264_vaapi -b:v 8M -f null - 2>&1 | tr '\r' '\n' |
| MS-02 Ultra - ada_cuda | intel_vaapi_hevc | 451 | 3 | 451 to 466 | 8.73 | distro ffmpeg (see inventory) | ffmpeg -hide_banner -benchmark -y -t 60 -i /var/tmp/bo-bench/assets/bbb-clip/bbb_1080p_60s.mp4 -an -vaapi_device /dev/dri/renderD128 -vf format=nv12,hwupload -c:v hevc_vaapi -b:v 6M -f null - 2>&1 | tr '\r' '\n' |
| MS-02 Ultra - ada_cuda | nvenc_h264 | 322 | 3 | 319 to 322 | 1.36 | distro ffmpeg (see inventory) | ffmpeg -hide_banner -benchmark -y -t 60 -i /var/tmp/bo-bench/assets/bbb-clip/bbb_1080p_60s.mp4 -an -c:v h264_nvenc -preset p5 -b:v 8M -f null - 2>&1 | tr '\r' '\n' |
| MS-02 Ultra - ada_cuda | nvenc_av1 | 393 | 3 | 392 to 393 | 0.556 | distro ffmpeg (see inventory) | ffmpeg -hide_banner -benchmark -y -t 60 -i /var/tmp/bo-bench/assets/bbb-clip/bbb_1080p_60s.mp4 -an -c:v av1_nvenc -preset p5 -b:v 5M -f null - 2>&1 | tr '\r' '\n' |
| MS-02 Ultra - igpu_arc | intel_vaapi_h264 | 400 | 3 | 398 to 412 | 7.76 | distro ffmpeg (see inventory) | ffmpeg -hide_banner -benchmark -y -t 60 -i /var/tmp/bo-bench/assets/bbb-clip/bbb_1080p_60s.mp4 -an -vaapi_device /dev/dri/renderD128 -vf format=nv12,hwupload -c:v h264_vaapi -b:v 8M -f null - 2>&1 | tr '\r' '\n' |
| MS-02 Ultra - igpu_arc | intel_vaapi_hevc | 427 | 3 | 414 to 441 | 13.4 | distro ffmpeg (see inventory) | ffmpeg -hide_banner -benchmark -y -t 60 -i /var/tmp/bo-bench/assets/bbb-clip/bbb_1080p_60s.mp4 -an -vaapi_device /dev/dri/renderD128 -vf format=nv12,hwupload -c:v hevc_vaapi -b:v 6M -f null - 2>&1 | tr '\r' '\n' |
| OneXStation (8060S) | vaapi_h264 | 441 | 3 | 441 to 442 | 0.435 | distro ffmpeg (see inventory) | ffmpeg -hide_banner -benchmark -y -t 60 -i /var/tmp/bo-bench/assets/bbb-clip/bbb_1080p_60s.mp4 -an -vaapi_device /dev/dri/renderD128 -vf format=nv12,hwupload -c:v h264_vaapi -b:v 8M -f null - 2>&1 | tr '\r' '\n' |
| OneXStation (8060S) | vaapi_hevc | 755 | 3 | 754 to 757 | 1.6 | distro ffmpeg (see inventory) | ffmpeg -hide_banner -benchmark -y -t 60 -i /var/tmp/bo-bench/assets/bbb-clip/bbb_1080p_60s.mp4 -an -vaapi_device /dev/dri/renderD128 -vf format=nv12,hwupload -c:v hevc_vaapi -b:v 6M -f null - 2>&1 | tr '\r' '\n' |
Power and heat
Under sustained GPU load, the card averaged 49 W and sat at its limit for the whole run, which in the chart lasts about 11.6 minutes. Its temperature climbed from 46 °C to a 79 °C peak and held there.
RTX 2000E Ada - ada_cuda peaks at 79°C under sustained GPU load
GPU temperature while the test holds the load (1 second samples). · °C · lower is better
View data table
| Series | x | Value (°C) |
|---|---|---|
| RTX 2000E Ada - ada_cuda | 1 | 46 |
| RTX 2000E Ada - ada_cuda | 15.6 | 61 |
| RTX 2000E Ada - ada_cuda | 23.9 | 65 |
| RTX 2000E Ada - ada_cuda | 39.6 | 69 |
| RTX 2000E Ada - ada_cuda | 46.9 | 71 |
| RTX 2000E Ada - ada_cuda | 62.6 | 72 |
| RTX 2000E Ada - ada_cuda | 69.9 | 73 |
| RTX 2000E Ada - ada_cuda | 85.5 | 74 |
| RTX 2000E Ada - ada_cuda | 93.9 | 74 |
| RTX 2000E Ada - ada_cuda | 108.5 | 75 |
| RTX 2000E Ada - ada_cuda | 116.8 | 75 |
| RTX 2000E Ada - ada_cuda | 132.5 | 76 |
| RTX 2000E Ada - ada_cuda | 139.8 | 76 |
| RTX 2000E Ada - ada_cuda | 155.4 | 76 |
| RTX 2000E Ada - ada_cuda | 162.7 | 76 |
| RTX 2000E Ada - ada_cuda | 178.4 | 77 |
| RTX 2000E Ada - ada_cuda | 186.8 | 77 |
| RTX 2000E Ada - ada_cuda | 201.4 | 77 |
| RTX 2000E Ada - ada_cuda | 209.7 | 77 |
| RTX 2000E Ada - ada_cuda | 225.4 | 77 |
| RTX 2000E Ada - ada_cuda | 241 | 77 |
| RTX 2000E Ada - ada_cuda | 248.3 | 77 |
| RTX 2000E Ada - ada_cuda | 264 | 77 |
| RTX 2000E Ada - ada_cuda | 271.3 | 77 |
| RTX 2000E Ada - ada_cuda | 286.9 | 77 |
| RTX 2000E Ada - ada_cuda | 295.3 | 78 |
| RTX 2000E Ada - ada_cuda | 309.9 | 78 |
| RTX 2000E Ada - ada_cuda | 318.3 | 78 |
| RTX 2000E Ada - ada_cuda | 333.9 | 78 |
| RTX 2000E Ada - ada_cuda | 341.2 | 78 |
| RTX 2000E Ada - ada_cuda | 356.9 | 78 |
| RTX 2000E Ada - ada_cuda | 364.2 | 78 |
| RTX 2000E Ada - ada_cuda | 379.8 | 78 |
| RTX 2000E Ada - ada_cuda | 388.2 | 78 |
| RTX 2000E Ada - ada_cuda | 402.8 | 78 |
| RTX 2000E Ada - ada_cuda | 411.1 | 78 |
| RTX 2000E Ada - ada_cuda | 426.7 | 78 |
| RTX 2000E Ada - ada_cuda | 434.1 | 78 |
| RTX 2000E Ada - ada_cuda | 449.7 | 78 |
| RTX 2000E Ada - ada_cuda | 457 | 78 |
| RTX 2000E Ada - ada_cuda | 472.7 | 78 |
| RTX 2000E Ada - ada_cuda | 488.3 | 78 |
| RTX 2000E Ada - ada_cuda | 496.7 | 78 |
| RTX 2000E Ada - ada_cuda | 511.3 | 78 |
| RTX 2000E Ada - ada_cuda | 519.6 | 78 |
| RTX 2000E Ada - ada_cuda | 535.3 | 78 |
| RTX 2000E Ada - ada_cuda | 542.6 | 78 |
| RTX 2000E Ada - ada_cuda | 558.2 | 78 |
| RTX 2000E Ada - ada_cuda | 565.5 | 78 |
| RTX 2000E Ada - ada_cuda | 581.2 | 78 |
| RTX 2000E Ada - ada_cuda | 589.5 | 79 |
| RTX 2000E Ada - ada_cuda | 604.1 | 79 |
| RTX 2000E Ada - ada_cuda | 612.5 | 79 |
| RTX 2000E Ada - ada_cuda | 628.1 | 79 |
| RTX 2000E Ada - ada_cuda | 635.4 | 79 |
| RTX 2000E Ada - ada_cuda | 651.1 | 79 |
| RTX 2000E Ada - ada_cuda | 658.4 | 79 |
| RTX 2000E Ada - ada_cuda | 674.1 | 79 |
| RTX 2000E Ada - ada_cuda | 682.4 | 79 |
| RTX 2000E Ada - ada_cuda | 697 | 79 |
Samples are thinned to about 90 points for the chart; the full 1 second series is in the run's samples file.
Thinned further to 60 points for the article page; every kept point is an original sample.
RTX 2000E Ada - ada_cuda averages 49 W under sustained GPU load
GPU power draw while the test holds the load (1 second samples). · watts · higher is better
View data table
| Series | x | Value (watts) |
|---|---|---|
| RTX 2000E Ada - ada_cuda | 1 | 7.02 |
| RTX 2000E Ada - ada_cuda | 15.6 | 50 |
| RTX 2000E Ada - ada_cuda | 23.9 | 50 |
| RTX 2000E Ada - ada_cuda | 39.6 | 50.1 |
| RTX 2000E Ada - ada_cuda | 46.9 | 50.5 |
| RTX 2000E Ada - ada_cuda | 62.6 | 49.9 |
| RTX 2000E Ada - ada_cuda | 69.9 | 50.1 |
| RTX 2000E Ada - ada_cuda | 85.5 | 49.9 |
| RTX 2000E Ada - ada_cuda | 93.9 | 49.9 |
| RTX 2000E Ada - ada_cuda | 108.5 | 50 |
| RTX 2000E Ada - ada_cuda | 116.8 | 49.9 |
| RTX 2000E Ada - ada_cuda | 132.5 | 49.9 |
| RTX 2000E Ada - ada_cuda | 139.8 | 50 |
| RTX 2000E Ada - ada_cuda | 155.4 | 49.9 |
| RTX 2000E Ada - ada_cuda | 162.7 | 50 |
| RTX 2000E Ada - ada_cuda | 178.4 | 49.9 |
| RTX 2000E Ada - ada_cuda | 186.8 | 49.9 |
| RTX 2000E Ada - ada_cuda | 201.4 | 49.9 |
| RTX 2000E Ada - ada_cuda | 209.7 | 49.9 |
| RTX 2000E Ada - ada_cuda | 225.4 | 49.9 |
| RTX 2000E Ada - ada_cuda | 241 | 50 |
| RTX 2000E Ada - ada_cuda | 248.3 | 50 |
| RTX 2000E Ada - ada_cuda | 264 | 49.9 |
| RTX 2000E Ada - ada_cuda | 271.3 | 50 |
| RTX 2000E Ada - ada_cuda | 286.9 | 49.9 |
| RTX 2000E Ada - ada_cuda | 295.3 | 49.9 |
| RTX 2000E Ada - ada_cuda | 309.9 | 49.9 |
| RTX 2000E Ada - ada_cuda | 318.3 | 49.9 |
| RTX 2000E Ada - ada_cuda | 333.9 | 50 |
| RTX 2000E Ada - ada_cuda | 341.2 | 50 |
| RTX 2000E Ada - ada_cuda | 356.9 | 49.9 |
| RTX 2000E Ada - ada_cuda | 364.2 | 49.9 |
| RTX 2000E Ada - ada_cuda | 379.8 | 49.9 |
| RTX 2000E Ada - ada_cuda | 388.2 | 50 |
| RTX 2000E Ada - ada_cuda | 402.8 | 49.9 |
| RTX 2000E Ada - ada_cuda | 411.1 | 50 |
| RTX 2000E Ada - ada_cuda | 426.7 | 49.9 |
| RTX 2000E Ada - ada_cuda | 434.1 | 49.9 |
| RTX 2000E Ada - ada_cuda | 449.7 | 49.9 |
| RTX 2000E Ada - ada_cuda | 457 | 49.9 |
| RTX 2000E Ada - ada_cuda | 472.7 | 49.9 |
| RTX 2000E Ada - ada_cuda | 488.3 | 49.9 |
| RTX 2000E Ada - ada_cuda | 496.7 | 50 |
| RTX 2000E Ada - ada_cuda | 511.3 | 49.9 |
| RTX 2000E Ada - ada_cuda | 519.6 | 49.9 |
| RTX 2000E Ada - ada_cuda | 535.3 | 50 |
| RTX 2000E Ada - ada_cuda | 542.6 | 49.9 |
| RTX 2000E Ada - ada_cuda | 558.2 | 49.9 |
| RTX 2000E Ada - ada_cuda | 565.5 | 49.9 |
| RTX 2000E Ada - ada_cuda | 581.2 | 49.9 |
| RTX 2000E Ada - ada_cuda | 589.5 | 50 |
| RTX 2000E Ada - ada_cuda | 604.1 | 49.9 |
| RTX 2000E Ada - ada_cuda | 612.5 | 50 |
| RTX 2000E Ada - ada_cuda | 628.1 | 49.9 |
| RTX 2000E Ada - ada_cuda | 635.4 | 50 |
| RTX 2000E Ada - ada_cuda | 651.1 | 49.9 |
| RTX 2000E Ada - ada_cuda | 658.4 | 49.9 |
| RTX 2000E Ada - ada_cuda | 674.1 | 49.9 |
| RTX 2000E Ada - ada_cuda | 682.4 | 49.9 |
| RTX 2000E Ada - ada_cuda | 697 | 49.9 |
Samples are thinned to about 90 points for the chart; the full 1 second series is in the run's samples file.
Thinned further to 60 points for the article page; every kept point is an original sample.
During that run, Llama 3.1 8B generation settled at 33.4 tok/s, against 42.3 tok/s in the short run. So a long session on this card is slower than a quick benchmark suggests, and at 79 °C there is little thermal headroom in a small chassis. We did not measure fan noise.
Efficiency is respectable. On gpt-oss-20b the whole machine drew 96.7 W at the wall in the ada_cuda run, which is 0.633 tok/s per watt; the default run drew 147.3 W for 0.437 tok/s per watt, and we cannot explain that gap. On Llama 3.1 8B the figure is 0.396 tok/s per watt, close to the Ryzen AI Max+ 395's 0.393.
The Arc iGPU comparison
The igpu_arc configuration did not produce llama.cpp results, so there is no LLM comparison with the Arc iGPU. Its whisper result is 16.1x in the CUDA variant, which shows the NVIDIA card was still active, so we would not use that run to judge the iGPU. Its encoder numbers, above, are genuine.
Verdict
The RTX 2000E Ada is a good fit for a specific job: running 8B to 20B models at conversational speed, transcribing audio quickly and rendering with OptiX, inside a 50 W budget in a compact machine. It is not a route to 30B-class or larger models; memory, not speed, is the wall. If you want those, you need more memory, not a faster 16 GB card. Price and noise were not measured, so factor those in yourself.
The card can be swapped in the MS-02 Ultra, so you are not locked into it. We tested it in this machine.
The numbers
| Memory | 16,380 MiB (16 GB class), driver 595.99.02 |
|---|---|
| Power | 50 W limit; 49 W average in the sustained run |
| Peak temperature | 79 °C |
| Llama 3.1 8B | 42.2 tok/s generation, 1,849 tok/s prompt (default run) |
| Qwen3 14B | 22.7 tok/s generation, 954 tok/s prompt (default run) |
| gpt-oss-20b | 64.3 tok/s generation, 1,625 tok/s prompt (default); 61.2 and 1,957 tok/s (ada_cuda) |
| Whisper large-v3-turbo | 15.2x real time (default), 16.0x (ada_cuda) |
| Blender BMW27 | 26.9 s CUDA, 13.0 s OptiX |
| NVENC | 371 fps HEVC, 322 fps H.264, 393 fps AV1 |
Some links below may earn us a commission at no cost to you. See our affiliate disclosure.
What we left out
Price, noise, warranty and availability. We also did not test other cards, so we make no claims about the RTX 2000E Ada against its rivals.